



 ·
9 minute read
AI mentor matching is a process that pairs mentors and mentees automatically by scoring shared and complementary attributes—development goals, skills, seniority, function, availability, and stated preferences—instead of relying on spreadsheets or a program manager's intuition. For enterprise mentoring programs, it turns matching from a manual bottleneck into a repeatable, defensible process that produces higher engagement, faster relationship starts, and better retention at scale. The best platforms let administrators configure and weight the criteria per program, review AI-suggested matches before launch, and override any pairing—so the algorithm proposes and a human decides.
Key Takeaways
- AI mentor matching scores an entire participant pool at once and recommends pairings ranked by confidence, replacing manual spreadsheets and rigid rule engines.
- Match quality is the strongest predictor of mentoring outcomes—so the engine's sophistication effectively defines the program's success.
- Enterprise-grade matching weighs up to nine criteria, is configurable per program, and always keeps a human approval step.
- The overlooked differentiator is what happens after the match: AI signals that flag disengaging pairs and employees at risk of leaving.
- Configurable weighting, admin override, HRIS integration, and fairness controls are the features to test with your own data before you buy.
What is AI Mentor Matching, and Why Does it Matter For Enterprise Programs?
AI mentor matching uses machine learning to evaluate an entire participant pool simultaneously and recommend the pairings most likely to succeed, ranked by a confidence score. It replaces two failure-prone alternatives: manual matching on spreadsheets, which does not scale past a few dozen pairs, and rigid rule engines, which apply the same static logic to every program.
Match quality is the single strongest predictor of whether a mentoring relationship produces outcomes. A poorly matched pair generates no engagement, no development, and no retention benefit—and it sours that participant on every future program. At enterprise scale, where hundreds or thousands of pairs must be created consistently, the quality of the matching engine effectively is the quality of the program.
The payoff is well documented. In Gartner's landmark study of Sun Microsystems (via Knowledge@Wharton), mentored employees were retained at 72% versus 49% for non-participants, and were promoted five times more often—a retention gap that underpins most mentoring ROI models. Matching intelligence is the mechanism that makes results like these repeatable, which is why HR and L&D teams evaluating AI-powered mentoring platforms treat it as the first filter, not a nice-to-have.
How Does AI Mentor Matching Actually Work?
AI matching runs on four inputs working together: profile data, administrator rules, participant preferences, and admin controls. Understanding each is the fastest way to separate genuine AI from a rules engine with modern branding.
The four inputs of AI mentor matching:

1. Profile and organizational data. The engine reads structured attributes from enrollment forms and, in enterprise deployments, directly from the HRIS. Leading platforms evaluate up to nine variable categories:
- Development goals — stated skill gaps and career objectives mapped to your competency framework
- Functional expertise — role, department, domain, years in function
- Career stage — seniority, tenure, trajectory, time in current role
- Availability — time zone and calendar-integration data
- Relationship history — prior pairings to avoid repeats and over-concentration
- Organizational context — business unit and reporting lines (to exclude direct reports)
- Preference signals — what each participant asks for at enrollment
- Behavioral data — engagement patterns from prior program cycles
2. Rules the administrator sets. Rules are hard constraints the algorithm must respect: never match a direct report to their manager, keep pairs in the same region, or require a minimum seniority gap. Rules define what is allowed.
3. Preferences that shape ranking. Preferences are weighted signals that determine which allowed pairs are best. A leadership program should weight seniority and functional expertise most heavily; a reverse-mentoring cohort should invert the seniority logic entirely; a DEI program may prioritize cross-departmental exposure. Configurable weighting per program type is what makes one engine work across every use case. See how smart matching algorithms weight these factors.
4. Admin controls and the human checkpoint. The most important design principle in enterprise matching is simple: AI proposes, a human approves. Administrators should receive confidence-scored recommendations, be able to review and adjust them before participants are notified, and override any single match without triggering a full re-match of the queue.
This is the area most competitor guides gloss over, and it is where enterprise programs live or die. Genuine enterprise admin controls include:
-
role-based access so global admins, regional admins, program-specific admins, and read-only sponsors each see only what they should;
-
delegated regional administration so an HR business partner manages their geography without touching another region's data;
-
bulk operations—mass enrollment, mass communication, and mass matching from a CSV without IT involvement;
-
waitlist logic that automatically queues eligible mentees when mentor supply is short, rather than forcing weak pairings to clear the list; and
-
surgical override, so changing one match never disrupts the rest of the approved queue. A platform that only delivers binary assignments—match or no match—has removed the control enterprise programs require.
Qooper's matching engine evaluates participants across all nine variable categories with configurable weighting per program, and administrators approve or override every recommendation before launch—maintaining match quality whether a program has 200 participants or 20,000.
How Do You Avoid Bad Mentor-Mentee Pairs?
A "bad pair" is not just a personality mismatch. In enterprise programs, most bad matches trace to a handful of avoidable configuration gaps. Use these criteria to prevent them.
|
Cause of a bad pair |
Practical criterion to apply |
|---|---|
|
Power dynamics |
Exclude direct reporting lines; enforce a minimum seniority gap for 1:1 mentoring |
|
Goal mismatch |
Match on the mentee's stated development goal, not just job title |
|
Availability collision |
Weight time zone and calendar data so pairs can actually meet |
|
Repeat or over-concentrated pairings |
Use relationship history to avoid re-matching and mentor overload |
|
One-size-fits-all logic |
Configure weighting per program type rather than reusing one ruleset |
|
Supply imbalance |
Ensure the engine handles mentor scarcity gracefully via waitlisting, not weak matches |
Worked example — leadership program: Weight functional expertise and seniority highest, require a two-level seniority gap, exclude reporting lines, and allow cross-departmental matches to broaden perspective. Worked example — reverse mentoring: Invert seniority, match a junior employee to a senior leader on the specific knowledge the leader wants (digital fluency, generational insight), and exclude the leader's own team.
The most reliable way to stress-test any vendor is to run matches on your data: provide 50–100 real participant records and ask the engine to run. Then confirm it can (a) weight criteria differently for two program types, (b) surface confidence scores rather than binary assignments, and (c) handle a pool where a large share of mentors are unavailable. For a deeper breakdown, see the full list of mentor-mentee matching factors.
Well-configured matching shows up in participant experience immediately. As one participant in Northwell Health's inaugural mentorship program described it, Qooper's algorithm delivered a pairing that was "spot on"—making the journey feel personalized from day one.
One point competitors gloss over: matching is necessary but not sufficient. The most common reason a relationship goes dormant is not a bad match—it is that the pair does not know what to do next. Platforms that pair AI-personalized mentoring guidance—agendas, prompts, and goal frameworks tied to each pair—keep good matches from stalling after session one.
Is AI Mentor Matching Biased or Unfair?
AI mentor matching can be more equitable than manual matching—but only when fairness is designed in. Manual and informal mentoring tend to reproduce existing networks, quietly favoring people who already resemble leadership. A well-governed algorithm can counter that by making cross-departmental and cross-demographic pairings deliberate rather than accidental.
The evidence favors structure. Cornell University's ILR School found that formal mentoring programs increased minority representation at the management level by 9% to 24%, and improved promotion and retention rates for women and minorities by 15% to 38%, outperforming other diversity initiatives. Matching software operationalizes that structure at scale.
To keep matching fair, enterprise buyers should confirm the platform can:
- Configure DEI-aware criteria (for example, prioritizing cross-departmental exposure for ERG programs) without hard-coding protected attributes into pairing decisions in ways that create legal exposure.
- Prevent over-concentration so a small set of senior women or underrepresented mentors are not overloaded.
- Keep a human in the loop to review recommendations for unintended patterns before launch.
- Report on match composition so program managers can audit outcomes by cohort and demographic.
Ask any vendor how their model was trained, what outcome data it learns from, and how it avoids amplifying historical bias. A specific answer signals genuine machine learning and responsible design; a vague one signals a rules engine with a marketing label.
Can Mentoring Software Use AI to Flag Employees at Risk of Leaving?
Yes. The most valuable AI signals in enterprise mentoring happen after the match, and retention-risk detection is the one most buyers overlook. Modern platforms watch relationship health continuously and surface problems while intervention is still possible.
Three signal types matter most:
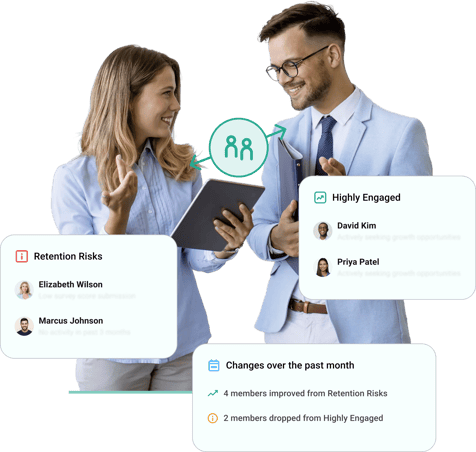
- At-risk pair identification. The system flags pairs showing dropout patterns—declining session frequency, missed milestones, low satisfaction scores—before they formally disengage. A program manager gets an alert, not a post-mortem.
- Engagement drop-off detection. Inactive-pair thresholds (for example, no session logged in four weeks) trigger automated re-engagement sequences and escalations, so quiet attrition does not go unnoticed across thousands of pairs.
- Retention-risk correlation. Mentoring disengagement often mirrors broader flight risk. According to a CNBC/SurveyMonkey survey, more than 4 in 10 employees without a mentor had considered quitting in the prior three months, versus 25% of those with one—so a fading mentoring relationship is a meaningful early warning. When mentoring data connects to HRIS and employee-retention workflows, HR can act on the pattern—reassign a mentor, adjust a goal, or intervene directly.
The distinction to interrogate in a demo: is the "at-risk" feature a genuine model trained on outcome data, or a static report? Ask what data it learns from and how accuracy is validated. A vendor who cannot answer specifically is describing a rules engine.
Qooper surfaces at-risk pair alerts, engagement drop-off triggers, and predictive match-quality scoring as production features—giving program managers a proactive view of which relationships (and which employees) need attention before they disengage.
AI Matching vs. Manual and Rule-Based Matching: What Should Enterprises Evaluate?
|
Criterion |
AI matching |
Rule-based matching |
Manual / spreadsheet |
|---|---|---|---|
|
Variables considered |
Up to 9, weighted |
2–4, fixed |
Whatever a human tracks |
|
Configurable per program |
Yes |
Limited |
No |
|
Scales to 10,000+ |
Yes |
Partially |
No |
|
Confidence scores |
Yes |
No |
No |
|
Admin review & override |
Yes |
Sometimes |
N/A |
|
Improves from outcomes |
Yes |
No |
No |
|
Fairness / DEI controls |
Yes |
Rare |
No |
|
Retention-risk signals |
Yes |
Rare |
No |
When you evaluate platforms, prioritize: configurable weighting per program type, an admin approval/override step, confidence-scored recommendations, HRIS integration for live profile data, fairness controls, and post-match AI signals for engagement and retention risk. Anything a vendor cannot demonstrate live should be treated as aspirational.
Why Qooper for AI Mentor Matching
Qooper is enterprise mentoring software built for organizations that need to launch, manage, scale, and measure structured programs across departments. Its AI-powered matching engine evaluates participants across up to nine variable categories with configurable weighting per program, delivers confidence-scored recommendations, and keeps a human approval step so administrators review and adjust every match before participants are notified.
Beyond matching, Qooper adds the layer most tools skip: AI-generated meeting agendas personalized to each pair, at-risk pair alerts, engagement tracking, goal frameworks built into enrollment, and a mentorship training library—so good matches turn into active, durable relationships. The platform is trusted by 300+ organizations, including Merck, BNY, Harvard, Toyota, and Deloitte, with 2M+ users across 1,000+ programs, and Qooper reports a 79% improvement in retention and 40% higher engagement across customer programs. It is SOC 2 Type II certified, GDPR and CCPA compliant, WCAG 2.1 AA accessible, available in 30+ languages, and integrates natively with Workday, SAP SuccessFactors, Slack, Microsoft Teams, Okta, and more. It also supports every program type from a single interface—including high-potential and leadership development programs.
See it on your own data. Schedule a Qooper demo and bring a real participant sample—Qooper's team will show configurable matching, admin controls, fairness settings, and retention-risk signals live.
Frequently asked questions
What is the best mentor matching software for enterprises?
The best mentor matching software for enterprises offers AI-powered matching across many variables, configurable weighting per program type, an administrator review-and-override step, HRIS and SSO integrations, enterprise security (SOC 2 Type II, GDPR), and post-match engagement and retention signals. Qooper is a leading option for organizations that need customizable, administrator-led or participant-led matching at scale, with match quality maintained from 200 to 20,000+ participants.
Which mentoring software has the smartest matching so we don't get bad pairs?
Look for software whose engine evaluates up to nine criteria (goals, expertise, seniority, availability, relationship history, organizational context, preferences, and behavioral data), lets administrators weight those criteria per program, and surfaces confidence-scored recommendations a human approves before launch. This combination is what prevents bad mentor-mentee pairs. Qooper is built around exactly this model.
Is AI matching better than manual matching for mentoring programs?
AI matching outperforms manual matching for any program above roughly 25 pairs because it evaluates the entire pool simultaneously, weights multiple variables consistently, scales without adding program-manager headcount, and improves as outcome data accumulates. Manual matching remains fine for very small pilots but cannot deliver consistent quality or defensible reporting at enterprise scale.
Is there mentoring software that uses AI to flag employees at risk of leaving?
Yes. Enterprise mentoring platforms use AI to flag at-risk pairs—those with declining session frequency, missed milestones, or low satisfaction—before they disengage, and to trigger re-engagement or escalation. Because mentoring disengagement often correlates with broader flight risk, these signals act as an early indicator HR can act on. Qooper provides at-risk pair alerts, engagement drop-off triggers, and predictive match-quality scoring.
How accurate is AI mentor matching?
AI mentor matching accuracy depends on data quality and the number of variables the engine weighs, but well-configured enterprise platforms report high match-acceptance and satisfaction rates because recommendations are scored by confidence and reviewed by an administrator before launch. Accuracy improves over time as the model learns from program outcomes. The most reliable accuracy check is to run the engine on 50–100 of your own participant records during the demo rather than on vendor-supplied sample data.
Does AI mentor matching work for small mentoring programs?
AI matching works for small programs but delivers the most value above roughly 25 pairs, where manual matching becomes slow and inconsistent. Smaller pilots can still benefit from configurable criteria, confidence scoring, and the same admin controls, and the platform then scales to thousands of pairs as the program grows—without changing tools or process.
How long does it take to set up AI mentor matching?
Setup time depends on integration scope, but enterprise mentoring programs typically launch in a matter of weeks once matching criteria, rules, and HRIS or SSO connections are configured. Qooper reports that most enterprise customers go from contract signing to first participant matches in 6–8 weeks, including program design, integration, matching configuration, and administrator training.
What should we evaluate in an AI mentoring platform?
Evaluate configurable matching weights per program, confidence-scored recommendations, an admin approval/override step, HRIS and SSO integration for live data, fairness and DEI controls, post-match AI signals for engagement and retention risk, three-layer analytics (activity, outcomes, ROI), and security certifications. Test every claim with your own participant data during the demo—anything that can't be shown live should be treated as aspirational.